A spam filter can get its rule from a programmer’s guess or from messages that people have already labelled. Build both on eight examples, count their mistakes by hand and in code, and learn the three things a program needs before it can be said to learn.
Explain the difference between a rule that a person writes and a rule that a program learns from labelled examples.
Count the mistakes a threshold rule makes on a small set of labelled examples, and say which kind each mistake is.
Find by hand, and then in code, the threshold that makes the fewest mistakes on a set of examples.
Name the three things a program needs in order to learn (a task, experience and a performance measure) and point to each of them in an example.
In review. The maths and code on this page are checked by automated tests on every change, but an independent reader has not signed it off yet. Spot a mistake or a confusing step? Tell us.
The question
You could write a spam filter in one line: flag every message with more than five exclamation marks. But why five? You guessed. Could the program find that number itself, from messages that people have already marked as spam, and find it again when the spammers change their habits?
Intuition
There are two ways to get a program that does a job.
Write the rule. A person thinks about the problem, decides on the rule and types it in. What the program knows came out of that person’s head.
Learn the rule. A person collects examples: cases where the right answer is already known. A second program, the learner, searches for a rule that gets those examples right. What the finished program knows came out of the examples.
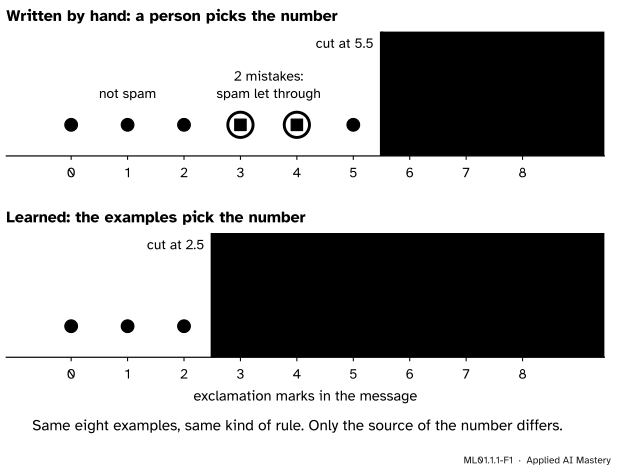
The job in this module is a small spam filter. Each message is described by one number, its count of exclamation marks. The rule has a fixed shape: flag the message as spam when its count is above some number. That number is the threshold, or the cut, because it cuts the number line in two. The only open question is where the cut goes.
ML01.1.1-F1
One kind of rule, two sources for its number. Top: a person guessed “more than five”, which puts the cut at 5.5 and lets two spam messages through. Bottom: a learner tried every cut on the eight examples and kept the one with the fewest mistakes.
That is the whole idea of machine learning: the rule is not typed in by a person. It is found by a procedure, from data.
Build it up
Step 1. Collect examples with their answers. Here are eight short messages. Someone read each one and wrote down whether it was spam. That answer is the message’s label.
The messages were invented for this module, so every count can be checked by hand. Counting exclamation marks is a real technique: Spambase, 4,601 emails collected at Hewlett-Packard Labs in 1999, records the percentage of each email’s characters that are !.
Step 2. Fix the shape of the rule. Write \(x\) for a message’s count of exclamation marks and \(c\) for the cut. The rule is: flag the message as spam if \(x > c\). We place cuts halfway between whole numbers, at \(0.5\), \(1.5\), \(2.5\) and so on, so that no message sits exactly on a cut. The hand-written rule “more than five” is the cut \(c = 5.5\).
Step 3. Count the mistakes of one rule. A rule makes a mistake on an example when its answer differs from the label. There are two kinds. A spam message at or below the cut is let through. A message that is not spam (a normal message) above the cut is flagged. For \(c = 5.5\), the spam with 3 and 4 marks is let through and no normal message is flagged. That is \({2 + 0 = 2}\) mistakes.
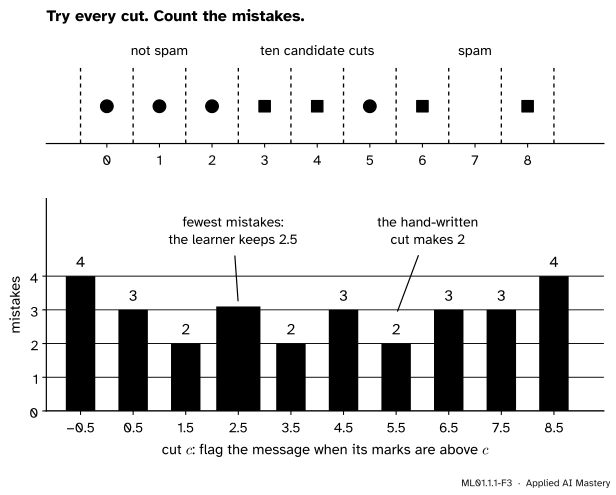
Step 4. Let a procedure choose the cut. Try each cut in turn, from \(-0.5\) (which flags every message) to \(8.5\) (which flags none), and keep the cut with the fewest mistakes. The worked example does all ten. The winner is \(c = 2.5\), with 1 mistake.
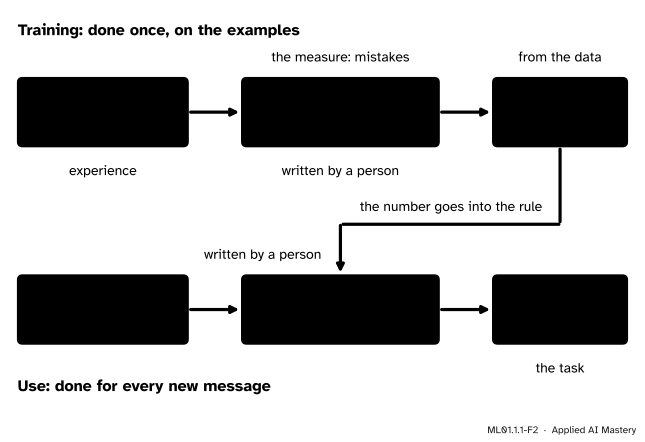
Step 5. See what was written and what was learned.
ML01.1.1-F2
The parts of a program that learns. A person wrote the shape of the rule and the learner. The number \(2.5\) was written by nobody: it came out of the examples. Other examples would give another number.
The formal statement
NoteDefinition: threshold rule
For a number \(c\), the threshold rule with cut \(c\) turns a count \(x\) into the prediction
The count comes from the message. The prediction\(\hat{y}\), read “y hat”, is the rule’s answer. The true label is \(y\), with \(1\) for spam and \(0\) for not spam. The cut is the only part of the rule that can change.
On \(n\) examples \((x_1, y_1), \dots, (x_n, y_n)\), the number of mistakes is the number of examples with \(\hat{y}_i \neq y_i\). It splits into the two kinds of Step 3, normal messages flagged and spam let through:
\[
\begin{aligned}
& \text{mistakes}(c) \\
& \quad = \#\{\, i : y_i = 0 \text{ and } x_i > c \,\} \\
& \quad + \#\{\, i : y_i = 1 \text{ and } x_i \le c \,\} .
\end{aligned}
\]
The sign \(\#\{\dots\}\) means “the number of examples for which this holds”.
NoteDefinition: the learner
List the candidate cuts: \(-0.5,\ 0.5,\ 1.5,\ \dots\) up to half a mark above the largest count.
For each candidate, count its mistakes on the examples.
Return the candidate with the fewest mistakes. If several tie, return the smallest.
Why ten candidates are enough. There are infinitely many cuts, yet the learner tries ten and misses nothing. Take two cuts \(c < c'\) and suppose no example has a count in the range \({c < x_i \le c'}\). Then the two rules agree on every example:
If \(x_i > c'\), then also \(x_i > c\), because \(c' > c\).
If \(x_i > c\), then \(x_i\) is not in the range \({c < x_i \le c'}\), so it lies above it: \(x_i > c'\).
So \(x_i > c\) exactly when \(x_i > c'\): the same answers, and the same number of mistakes.
Our counts are whole numbers from 0 to 8. Any cut from a whole number \(k\) up to, but not including, \({k + 1}\) has no count between it and \({k + 0.5}\), so it behaves like \({k + 0.5}\). Any cut below 0 behaves like \(-0.5\), and any cut from 8 upwards like \(8.5\). The ten candidates cover every way a threshold rule can behave on these messages. It also means the data cannot tell \(2.5\) from \(2.9\): placing a cut halfway is a convention.
NoteDefinition: learning (Mitchell, 1997)
“A computer program is said to learn from experience \(E\) with respect to some class of tasks \(T\) and performance measure \(P\), if its performance at tasks in \(T\), as measured by \(P\), improves with experience \(E\).”
In general
In this lesson
Task \(T\)
What the program must do
Decide, for a message, spam or not spam
Experience \(E\)
What it learns from
Messages that already carry a label
Performance measure \(P\)
How its work is scored
The share of messages it gets right
The last three words carry the weight: improves with experience. A program with a hand-written cut can do the task and can be scored, but more examples never change it. It does not learn.
Worked example
Learn the cut from the eight examples by hand.
Sort the messages by their count: \(0, 1, 2\) (not spam), \(3, 4\) (spam), \(5\) (not spam), \(6, 8\) (spam). For each candidate cut, list the counts above it. Those messages are flagged. Then add the two kinds of mistake: normal messages flagged, plus spam let through.
Cut \(c\)
Counts above the cut
Flagged + let through
\(-0.5\)
all eight
\({4 + 0 = 4}\)
\(0.5\)
\(1, 2, 3, 4, 5, 6, 8\)
\({3 + 0 = 3}\)
\(1.5\)
\(2, 3, 4, 5, 6, 8\)
\({2 + 0 = 2}\)
\(2.5\)
\(3, 4, 5, 6, 8\)
\({1 + 0 =}\)1
\(3.5\)
\(4, 5, 6, 8\)
\({1 + 1 = 2}\)
\(4.5\)
\(5, 6, 8\)
\({1 + 2 = 3}\)
\(5.5\)
\(6, 8\)
\({0 + 2 = 2}\)
\(6.5\)
\(8\)
\({0 + 3 = 3}\)
\(7.5\)
\(8\)
\({0 + 3 = 3}\)
\(8.5\)
none
\({0 + 4 = 4}\)
ML01.1.1-F3
The table as a picture. Each dashed line in the top panel is one candidate cut, and the bar under it counts that cut’s mistakes.
As the cut moves right, fewer normal messages are flagged and more spam is let through. The total is smallest at \(c = 2.5\), with 1 mistake. That is the learner’s answer. The rows for \(6.5\) and \(7.5\) are equal because no message has 7 marks.
One mistake is left. Happy birthday!!!!! has 5 marks and is not spam, yet it sits among the spam. To let it through, the cut must be at 5 or above, and then the spam with 3 and 4 marks gets through as well. No cut gets all eight right.
Use the rule. A new message arrives with 4 exclamation marks. Since \(4 > 2.5\), it is flagged. A message with 1 mark is not, since \(1 > 2.5\) is false.
Code
First the rule and its mistake count, in plain Python.
marks = [0, 1, 2, 5, 3, 4, 6, 8] # exclamation marks in each messagespam = [0, 0, 0, 0, 1, 1, 1, 1] # the label: 1 = spam, 0 = not spamdef predict(count, cut):"""The threshold rule: 1 (spam) when the count is above the cut."""return1if count > cut else0def mistakes(cut, counts, labels):"""How many examples the rule with this cut gets wrong."""returnsum(predict(x, cut) != y for x, y inzip(counts, labels))print("hand-written cut 5.5:", mistakes(5.5, marks, spam), "mistakes")
hand-written cut 5.5: 2 mistakes
Now the learner. It is four lines long, and the number 2.5 is not in it.
def learn(counts, labels):"""Try every cut from -0.5 to max + 0.5. Return the first one with the fewest mistakes.""" cuts = [k -0.5for k inrange(max(counts) +2)]returnmin(cuts, key=lambda cut: mistakes(cut, counts, labels))for cut in [k -0.5for k inrange(10)]:print(f"cut {cut:4.1f}, mistakes: {mistakes(cut, marks, spam)}")cut = learn(marks, spam)print("the learner keeps", cut)
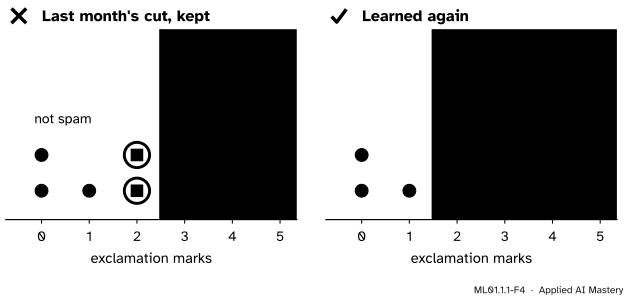
The column matches the table. Next month the spammers use fewer exclamation marks. Here are eight new labelled messages. The learner’s code stays the same.
hand-written cut 5.5: 4 mistakes
last month's cut 2.5: 3 mistakes
learned again: 1.5 with 1 mistake
Does the learner improve with experience? To test that, we make up messages with a random recipe: half are spam, a normal message has 1.5 marks on average and a spam message 5. Each learner gets \(n\) examples, and its cut is scored on 20,000 fresh messages.
import numpy as nprng = np.random.default_rng(0)def inbox(n):"""n made-up messages: half are spam; normal ones average 1.5 marks, spam averages 5.""" labels = rng.integers(0, 2, size=n) counts = rng.poisson(np.where(labels ==1, 5.0, 1.5))return counts.tolist(), labels.tolist()fresh_counts, fresh_labels = inbox(20_000) # messages that no learner gets to seedef share_right(cut):return1- mistakes(cut, fresh_counts, fresh_labels) /len(fresh_counts)print(f"hand-written cut 5.5: {share_right(5.5):.2f} of the fresh messages right")results = {}for n in [2, 8, 32, 128]: scores = [share_right(learn(*inbox(n))) for _ inrange(100)] # 100 learners, n examples each results[n] =float(np.mean(scores))print(f"learned from {n:3d} examples: {results[n]:.2f} right, on average")
hand-written cut 5.5: 0.69 of the fresh messages right
learned from   2 examples: 0.70 right, on average
learned from   8 examples: 0.78 right, on average
learned from  32 examples: 0.82 right, on average
learned from 128 examples: 0.84 right, on average
A cut learned from 2 examples is right on about 70% of fresh messages. With 8 examples it is 78%, with 32 it is 82% and with 128 it is 84%. Performance rises with experience. The hand-written rule stays at 69%.
Last, the library version. In scikit-learn a threshold rule is a decision tree of depth 1.
from sklearn.tree import DecisionTreeClassifierX = np.array(marks).reshape(-1, 1) # one row per message, one columnstump = DecisionTreeClassifier(max_depth=1, random_state=0).fit(X, spam)print("scikit-learn's cut:", stump.tree_.threshold[0])print("its mistakes:", int((stump.predict(X) != np.array(spam)).sum()))
scikit-learn's cut: 2.5
its mistakes: 1
The library finds the same cut. It scores cuts by how mixed the two sides are, not by the plain count of mistakes. On these eight messages both measures prefer \(2.5\).
Explore
ML01.1-X1
Rule versus learner
Drag the vermillion cut, or use its slider, to write the rule by hand, and watch the count of mistakes. Then press Run the learner and let the examples choose. Move, add or relabel a message and see which cut follows.
Two things to try.
Before you run the learner, find a cut with only one mistake. The bars under the number line show the count for every cut.
Run the learner, then press Next month. The learned cut follows the new messages. Yours stays where you left it.
The number line runs to 10, so it has twelve bars. The learner stops half a mark above the largest count, as defined above: ten cuts here.
Pitfalls
ML01.1.1-F4
Wrong beside right. The messages changed and the old cut did not. Learning again from the new examples moves the cut from \(2.5\) to \(1.5\).
“Once the rule is learned, the job is done.”
A learned rule fits the examples it came from. When the world changes, the rule goes out of date. On next month’s messages the old cut of \(2.5\) makes 3 mistakes and the hand-written \(5.5\) makes 4. Learning again brings it back to 1.
“A computer found the rule, so the rule is right.”
The learned cut still gets one message in eight wrong. It is the best cut for these examples and for this shape of rule. Lessons 2 and 3 take up those two limits.
“Learning means the program rewrites itself.”
Not one line of code changed when the cut moved from \(2.5\) to \(1.5\). The learner is a fixed program, and what it produces is a number. Later models hold millions of such numbers. Training them still changes numbers, never code.
“Learned rules are always better than written ones.”
When you can state the rule exactly, write it. Nobody should learn sales tax from examples. Learning earns its place when no one can write the rule down but examples are plentiful: which messages are spam, or what a photo shows.
Check yourself
Recall
1. Where does the number in a hand-written rule come from, and where in a learned rule?
Show answer
A person chooses it. In a learned rule the learner finds it from examples whose answers are known.
2. What are the two kinds of mistake a threshold rule for spam can make?
Show answer
It can let a spam message through, or flag a normal message.
3. How does this lesson’s learner choose its cut?
Show answer
It tries every candidate cut, counts each one’s mistakes on the examples, and keeps the cut with the fewest. On a tie it keeps the smallest.
4. Name the three things in Mitchell’s definition of learning.
Show answer
A task \(T\), experience \(E\) and a performance measure \(P\). The program learns if its performance at \(T\), measured by \(P\), improves with \(E\).
5. The examples change. What happens to a hand-written rule, and to a learned one?
Show answer
The hand-written rule stays until a person rewrites it. The learned rule changes as soon as the learner is run on the new examples.
Exercises
1.★ On the eight messages of this lesson, count the mistakes of the cut \(c = 3.5\) and of the cut \(c = 0.5\). Say which kind each mistake is.
Show solution
For \(c = 3.5\) the counts above the cut are \(4, 5, 6, 8\). The normal message with 5 marks is flagged and the spam with 3 marks is let through: \({1 + 1 = 2}\) mistakes.
For \(c = 0.5\) the counts above the cut are \(1, 2, 3, 4, 5, 6, 8\). The normal messages with 1, 2 and 5 marks are flagged and no spam is let through: \({3 + 0 = 3}\) mistakes.
2.★★ Six new messages have these counts. Not spam: \(1, 2, 4\). Spam: \(3, 5, 7\). Run the learner by hand. Which cut does it return, and what is unusual here?
Show solution
The candidates run from \(-0.5\) to \(7.5\). Their mistakes, in order, are
\[
3,\ 3,\ 2,\ 1,\ 2,\ 1,\ 2,\ 2,\ 3 .
\]
The cut \(2.5\) flags the counts \(3, 4, 5, 7\): one normal message (4) is flagged. The cut \(4.5\) flags \(5, 7\): one spam (3) is let through.
Two cuts tie with 1 mistake, and the learner returns the smaller, \(c = 2.5\). They are different rules, and the examples cannot choose between them. Which is better depends on which mistake you mind more.
3.★★★ Losing a real message is worse than seeing one spam. Suppose flagging a normal message costs 3 points and letting a spam through costs 1. Score every cut of the worked example by its total cost and find the best. What changed, and what did not?
Show solution
Take the two numbers in the last column of the table and compute
The lowest cost is 2, at \(c = 5.5\), which happens to be the hand-written cut.
The examples and the learner’s procedure did not change. Only the performance measure changed, and the learned rule followed it. Choose \(P\) with care: the learner chases whatever it rewards.
Summary card
A learned rule gets its number from examples, not from a person.
ML01.1.1-F1
Same rule shape, two sources.
Threshold rule. Predict spam when the count is above the cut: \({\hat{y} = 1}\) if \(x > c\), else \(0\).
Mistakes. Normal messages above the cut, plus spam at or below it.
Learner. Try every candidate cut, count mistakes, keep the fewest. Here \(c = 2.5\), with 1 mistake in 8.
Learning. A task \(T\), experience \(E\) and a performance measure \(P\), with \(P\) improving as \(E\) grows.
Sources and next steps
Sources. Each was opened and checked against this lesson on 12 November 2026.
Tom M. Mitchell, Machine Learning, McGraw-Hill, 1997 (free PDF). Section 1.1, page 2, gives the definition quoted above and names the three features of a well-posed learning problem: task, performance measure and experience.
Arthur L. Samuel, Some Studies in Machine Learning Using the Game of Checkers, IBM Journal of Research and Development, 3(3), 1959. The introduction draws this lesson’s contrast: without learning, methods must be specified “in minute and exact detail”.
Mark Hopkins, Erik Reeber, George Forman and Jaap Suermondt, Spambase, UCI Machine Learning Repository, 1999: 4,601 emails with 57 features, from Hewlett-Packard Labs according to its documentation file. Its char_freq_! feature is the percentage of an email’s characters that are exclamation marks.